
An effective incident response plan follows five phases: preparation, detection and analysis, containment, eradication and recovery, and post-incident activity. The moment a security event is suspected, the first action is to declare the incident and assign an Incident Manager, a step NIST SP 800-61 revision 3 and CISA guidance both treat as foundational.
TL;DR:
- Maintaining an offline, printed copy of the incident response plan and contact list ensures access during network outages or ransomware incidents.
- Regularly updating and testing playbooks, contact lists, and response procedures every quarter helps prevent delays and outdated actions during actual incidents.
- Assigning a designated Incident Manager with authority to make quick decisions is crucial, with clear escalation paths and roles documented in advance.
- Outsourcing 24/7 monitoring to a managed provider, combined with an internal Incident Manager, can significantly reduce detection and response times for small businesses.
- Preserving volatile memory evidence by isolating affected systems rather than powering them off is essential for forensic collection and legal compliance.
Table of Contents
- 1. Preparation: policy, inventory, playbooks, and training
- 2. Detection and analysis: triage, declaration, and evidence preservation
- 3. Containment, eradication, and recovery: getting back online safely
- 4. Communications and legal notifications: who to tell and when
- 5. Testing and exercises: from tabletop drills to after-action reports
- 6. Roles, team structure, and playbook authority
- 7. Post-incident activity: retrospectives and plan updates
- Small business realities and when to outsource incident response
- How Great Plains Networking supports incident readiness
- Where to go deeper: standards and templates worth bookmarking
- Sources
- FAQ
1. Preparation: policy, inventory, playbooks, and training
Preparation determines whether the rest of the plan works under pressure. CISA's Incident Response Plan Basics guidance recommends that the written plan receive formal approval from senior leadership, not just IT sign-off, and that printed or offline copies exist for the day your network is the thing that's down.
Beyond leadership approval, four artifacts need to exist before an incident, not during one.
- Maintain a current inventory of assets, logs, and telemetry sources tied to what your monitoring tools actually watch.
- Build playbooks and runbooks for common scenarios: ransomware, business email compromise, and data exfiltration each demand different first moves.
- Keep contact lists for staff, vendors, and external responders current and stored offline, since email and directory services may be unavailable during an incident.
- Pre-select an external forensics firm and legal counsel, and document their contractual access rights before you need them, a point covered in our IT services checklist for small businesses.
Training and testing round out preparation. CISA's guidance also calls for quarterly plan reviews and scheduled tabletop exercises, a cadence that keeps the plan from going stale between real incidents.
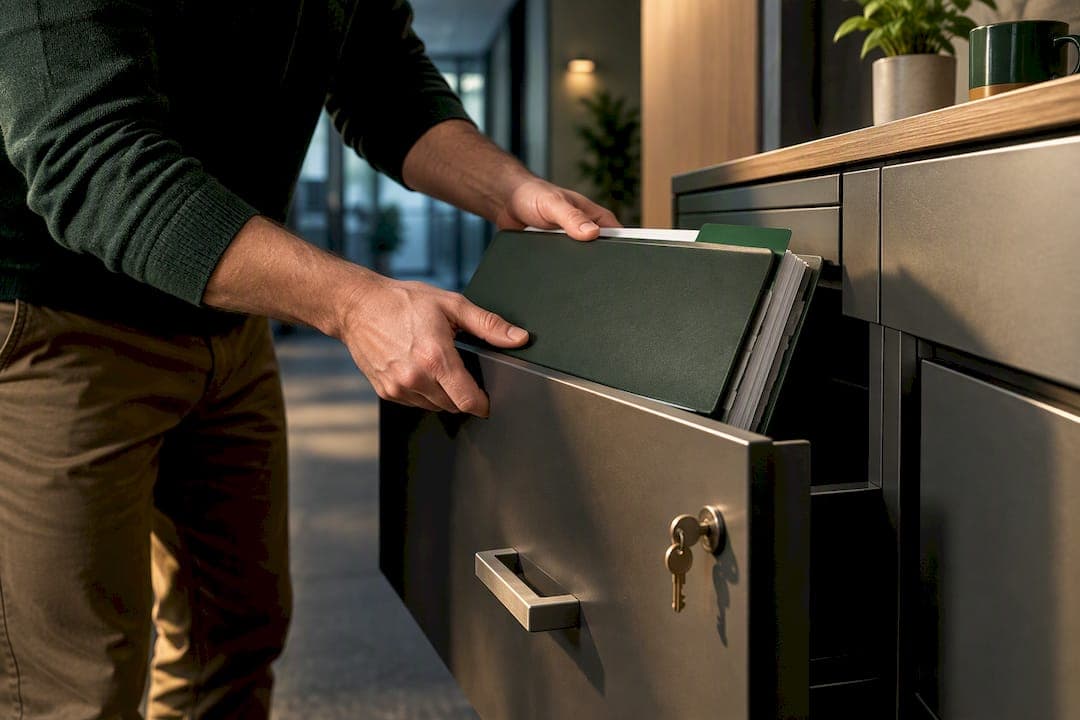
Pro Tip: Store one physical, printed copy of the IR plan and contact list off-network. If ransomware locks your file servers, that binder in a locked drawer is the only version you can actually open.
2. Detection and analysis: triage, declaration, and evidence preservation
Detection starts with telemetry: endpoint detection and response tools, firewall and network logs, email security gateways, and user reports each generate alerts that someone specific needs to own. A help desk technician who owns phishing reports and a network administrator who owns firewall alerts should both know it's their job before the alert fires.
Once an alert lands, a consistent triage sequence prevents both overreaction and dangerous delay:
- Verify the alert is real and not a false positive by checking the underlying log data.
- Scope the event: which systems, accounts, or data are affected right now.
- Assign a severity level based on business impact, data sensitivity, and spread.
- Document initial findings, timestamps, and the analyst's actions in an incident log.
- Declare the incident formally once severity crosses your predefined threshold, triggering full IR activation.
Evidence preservation rules matter from the first minute. PCI guidance cautions against powering off affected systems, since that can destroy volatile memory evidence, recommending isolation from the network instead while maintaining a documented chain of custody for anything collected. CISA's Federal Government Cybersecurity Incident and Vulnerability Response Playbooks recommend broad telemetry and centralized logging precisely so this triage can happen fast, without hunting across disconnected systems for the data an analyst needs. Our proactive cybersecurity guide covers how continuous monitoring shortens this window in practice.
3. Containment, eradication, and recovery: getting back online safely
Short-term containment buys time without destroying evidence. The right choice depends on what's spreading: isolating a single infected host works for contained malware, while blocking indicators at the firewall or disabling a compromised account stops lateral movement across the network. Every containment action should have a documented reason, since a rushed decision can tip off an attacker or wipe forensic evidence.
Eradication follows containment once the scope is understood.
- Remove malicious artifacts, unauthorized accounts, and persistence mechanisms from every affected system.
- Apply the patches that closed the original vulnerability before reconnecting anything.
- Reimage compromised machines from verified, clean backups rather than attempting to clean them in place.
- Validate that persistence mechanisms are actually gone before declaring eradication complete.
CISA's federal playbooks describe reimaging from gold backups and removing artifacts as the core eradication steps, paired with coordinated internal and perimeter containment. Recovery then happens in stages: validate systems in an isolated environment, bring services back online in a phased order based on business priority, and monitor closely for signs the threat actor is still present.
PCI DSS Requirement 12.10 requires designated personnel be available around the clock to respond to security alerts, a staffing reality that shapes whether eradication happens in hours or days.
Sometimes eradication has to pause. When law enforcement is involved or the incident may lead to litigation, hold off on wiping systems until forensic collection is complete and counsel has signed off.

4. Communications and legal notifications: who to tell and when
Notification decisions move fast once an incident is declared, and they should never happen ad hoc. Build the escalation chain in advance: who tells the board, who tells customers, and who determines whether regulators or law enforcement need a call.
- Predefine notification lists so no one is guessing who's on the distribution list at 2 a.m.
- Route every external notification, customer, press, or regulatory, through legal counsel before it goes out.
- Keep holding statements and a media playbook drafted ahead of time, along with customer notification templates for jurisdictions where breach laws require them.
- Map regulatory triggers in advance, since breach notification laws and contractual timelines (PCI among them) often start a countdown clock the moment an incident is confirmed.
Pro Tip: Draft your regulatory notification templates during a calm month, not during the incident. Tools like PromptChief's compliance checklist templates can help structure that documentation ahead of time.
5. Testing and exercises: from tabletop drills to after-action reports
Testing maturity builds in stages, and skipping ahead undermines the whole exercise.
- Start with a document review to confirm the plan reflects current systems and contacts.
- Run a walkthrough where the team talks through roles without acting them out.
- Conduct a full tabletop exercise (TTX) using a realistic scenario.
- Test individual components, like the notification chain, under simulated pressure.
- Run a full-scale exercise that exercises technical response alongside communications.
CISA's Tabletop Exercise Packages (CTEPs) offer a shortcut here, providing ready-made scenario modules, facilitator handbooks, and After-Action Report and Improvement Plan templates that standardize how a test gets scored and followed up.
Common pitfalls repeat across organizations that skip this discipline:
- Relying on a plan that exists only as a file on the same server an incident might lock.
- Working from a contact list that's months out of date.
- Waiting until the incident is underway to assign the Incident Manager.
Track metrics like time-to-detect and time-to-contain across each exercise, and schedule tests regularly to maintain readiness, according to CISA's recommendations.
6. Roles, team structure, and playbook authority
Clear roles prevent the worst kind of incident delay: two people assuming someone else has already acted. The Incident Manager coordinates the response and makes business-impact decisions; the Tech Lead runs technical remediation. Keeping those roles separate means the person negotiating a system shutdown with a client isn't also the one hunting for malware persistence, and decisions move faster because no one is switching between the two mindsets.
- Maintain an on-call roster with 24/7 coverage so alerts get a human response outside business hours.
- Document escalation paths for forensics, legal counsel, and law enforcement engagement.
- Review and update playbooks after every exercise and every real incident.
- Set an authority matrix in writing: who can isolate a system, revoke credentials, or approve a vendor engagement without waiting for a committee.
7. Post-incident activity: retrospectives and plan updates
Closing out an incident matters as much as responding to it. Run a formal, blameless retrospective that reviews the timeline and assigns specific remediation owners, focusing on what the process missed rather than who made a call under pressure.
- Walk the full incident timeline with everyone who touched it.
- Identify what worked, what didn't, and where the plan gave unclear guidance.
- Update the IR plan, playbooks, and training materials based on those findings.
- Communicate the changes to staff so the next incident benefits from this one.
- Log the incident and track every remediation action item to closure.
Measuring time-to-detect and time-to-recover across incidents shows whether the program is actually improving or just generating paperwork.
Small business realities and when to outsource incident response
Most small organizations can't staff a 24/7 security operations center, and trying to fake it with an unmonitored inbox is worse than admitting the gap. Pairing an internal Incident Manager who retains decision rights with a managed provider's round-the-clock monitoring often closes that gap faster than hiring alone would.
— Nicholas
How Great Plains Networking supports incident readiness
Building the plan is one thing; having someone watching at 3 a.m. is another. Great Plains Networking pairs 24/7 monitoring with plain-language support for small businesses across Norman, Moore, and Oklahoma City, so detection doesn't depend on someone noticing an alert days late.
- Cybersecurity support, including playbook creation and remediation help.
- Backup & Recovery services built for staged restoration after an incident.
- A free network assessment or a 10-minute readiness audit to see where your current plan has gaps.
Where to go deeper: standards and templates worth bookmarking
Start with NIST SP 800-61 revision 3 for the full lifecycle framework, and CISA's Incident Response Plan Basics for a practical build-out checklist. For testing, CISA's tabletop exercise packages include scenario libraries and after-action templates ready to adapt. Our Microsoft 365 security checklist covers related cloud hardening steps worth pairing with your plan.
Sources
FAQ
What are the main steps of an incident response plan?
The core steps are preparation, detection and analysis, containment, eradication and recovery, and post-incident activity, a structure drawn from NIST SP 800-61. Each phase produces specific artifacts, from documented playbooks in preparation to a retrospective report at the close.
Who should be the Incident Manager during a cyberattack?
The Incident Manager should be someone with authority to make business decisions quickly, separate from the person doing technical remediation. CISA's guidance recommends assigning this role in advance, since waiting until an incident is underway is a documented cause of delayed response.
How often should we run tabletop exercises?
Testing maturity builds from document reviews to full tabletop exercises, and CISA recommends a quarterly cadence for higher-risk organizations. CISA's tabletop exercise packages provide ready-made scenarios to run these without building materials from scratch.
Should a small business outsource incident response?
Many small businesses lack the staff for continuous monitoring, making a managed provider's 24/7 coverage a practical complement to an internal Incident Manager who keeps final decision authority. Great Plains Networking offers managed IT support built around this kind of shared responsibility for businesses in Norman, Moore, and Oklahoma City.
What should never happen when preserving evidence during an incident?
Affected systems should not be powered off, since that can erase volatile memory evidence investigators need. PCI guidance instead recommends isolating the system from the network and documenting every action taken as part of a clear chain of custody.